Metal fabrication manufacturer · 2026
Laser cutting list from Monitor ERP
Monitor ERP data for laser cutting in a fixed format: only parts nobody has planned yet, always fresh, with correct dates and no copying by hand.
Goal
The list's job was to pull the data laser cutting needs out of Monitor ERP with a fixed formula and in a fixed format. Production planning itself happens in Monitor, which runs online and is the production database. The list doesn't replace it. It takes only what the laser needs out of Monitor, such as parts not yet planned, the part code with the right revision and the material marks, and hands it on in the form the laser needs, without anyone writing data out or reformatting it by hand.
Results in numbers
What changed
Before 9.7 s
0.5 s
writing the data into Excel, about 20× faster
Before 2,000
4600+
rows reach the list; the old copy cut off at 2,000
Before all
0
already-planned parts that have to be picked out of the list by hand
Before 107 spellings
1 format
revision numbers in one format, as in the drawing file names (.r1, .p0)
Before manual
2 min
auto-refresh interval, and old data turns red
The situation
At a metal fabrication company, production planning happens in Monitor ERP, which runs online and is the whole production database. Laser cutting, though, needs data from it in a fixed form: only parts not yet planned, part codes with the right revision, material status and dates. One Excel file gathered all that from Monitor. Over the years it had turned into a tangle of SQL queries, API calls, Excel data connections, filters and VBA macros, all depending on each other. Change one piece and something broke somewhere else, and nobody knew any more exactly what depended on what.
On top of that, the file’s reports were written for the database of Monitor’s old version, G4, while the data now came from G5. There almost every table and field has a different name, so the file’s queries had to be rewritten one by one.
The list itself had problems too. It included parts that were already planned. Some rows quietly disappeared after a few days. Dates could be off by a day. A big part of the data never reached the list at all. In the end, the list couldn’t really be trusted.
Most of the work wasn’t writing code but investigating. On Monitor’s screen every column has a clear name, but the database has over 1,500 tables and nothing says which field matches which column on screen. I checked every guess the same way: I took a few orders whose correct answer I knew from the screen and looked at whether the database gave the same. Some guesses held up, some turned out to be exactly backwards, and some values weren’t in the database at all. Each problem below also says what didn’t work the first time.
Constraints
- The production software itself couldn't be changed. Data could only be read, and not a single operation could be moved in Monitor, not even for a test.
- The database has over 1,500 tables, most of them renamed in G5. Nothing documents which screen column matches which field, and SQL Anywhere's system tables differ from other databases', so even listing one table's columns took several tries.
- Queries ran on the client's computer over a remote connection and the results came back one at a time. Every wrong guess cost time, so every check query had to be thought through first.
- The most important piece of information, whether a part is already planned, wasn't written down anywhere.
- The list's format had to stay the same, because laser cutting uses the data in exactly that form. Excel is only the link between Monitor and laser cutting here, not a place where anyone works.
- Several bugs only showed up after days of real use. One test run proved nothing.
Solution
How I solved it
G4 → G5
The file's reports (bill of materials, stock, planning, order and delivery lists) read data in the shape of the Monitor G4 database. In G5 almost every name was different.
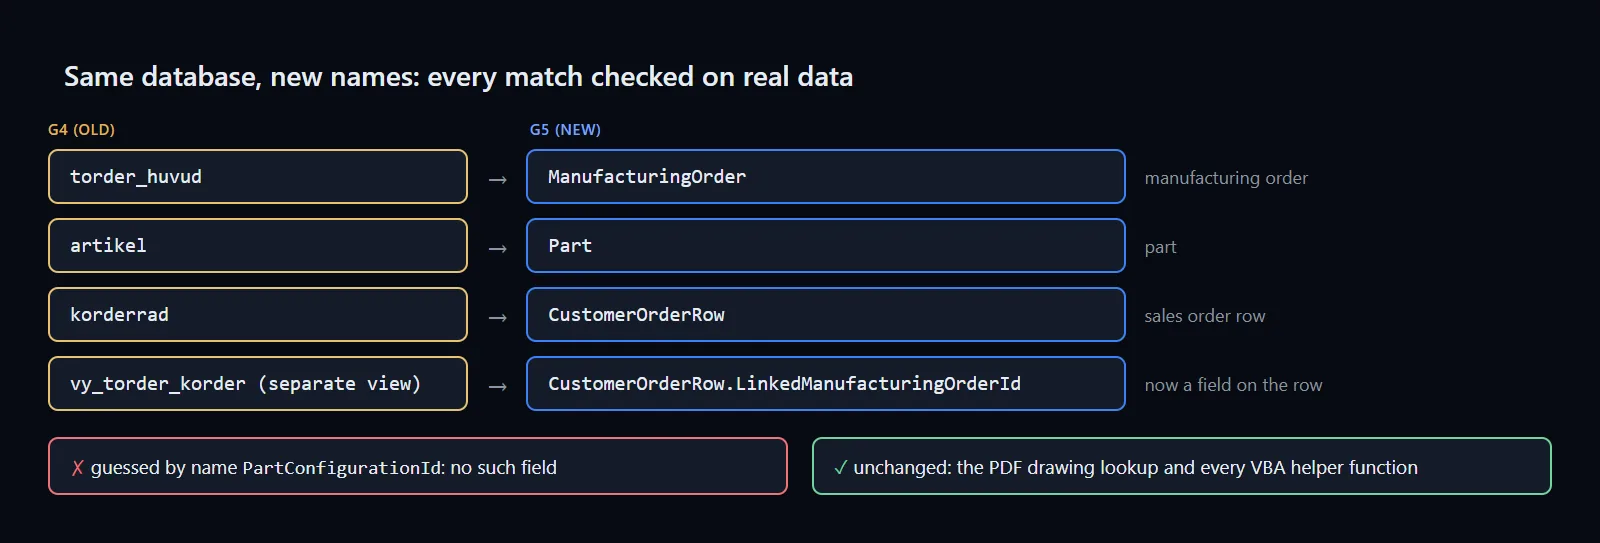
G4 tables had Swedish abbreviations: a manufacturing order was torder_huvud, a part artikel, a sales order row korderrad. In G5 they are ManufacturingOrder, Part and CustomerOrderRow, and the fields changed the same way. Some old tables split in two in the new system, addresses for example, and some links that used to live in a separate view are now a single field on the row.
I went through the reports one at a time, simplest first. Every table and field match went into one mapping document, together with whether it was confirmed on real data or still a guess. That way the next report didn’t have to work out the same things again.
What didn’t work: guessing by name. In the delivery list, the old “header part number” seemed to map to a field called PartConfigurationId, but the part table had no such field and the query failed. The right match only turned up once I went through all 141 of the sales order row’s fields with real data. That also showed that the manufacturing order number, which came from a separate view in G4, sits right on the row in G5.
One thing luckily stayed the same. The path to a part’s PDF drawing is found through the old file tables, which still exist in G5 and work unchanged. None of the VBA helper functions (finding pictures, inserting PDFs, building filters) needed changes either, because they don’t touch the database. So the work stayed within the queries, and the list format laser cutting uses stayed the same.
Data
The list included parts that were already planned, and they had to be picked out by hand.
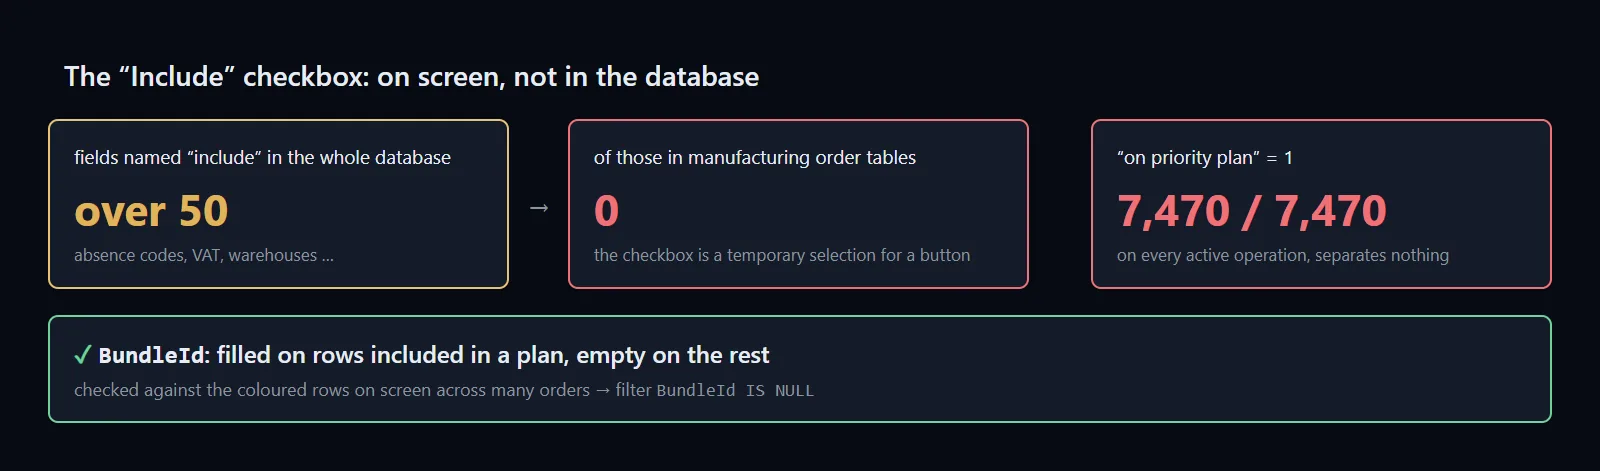
What didn’t work: the first candidate was the priority plan’s “Include” checkbox, because on screen it showed up next to the right rows. I searched the database for every field with “include” in its name. There were over fifty, from absence codes to VAT rates, but none belonged to manufacturing orders. Monitor’s manual confirmed why: the checkbox is only a temporary selection the planner uses to mark rows for a button action (rescheduling, for example), and it’s never saved to the database. The one similar field, “is the operation on the priority plan”, had the same value on all 7,470 active operations, so it separated nothing.
What finally worked: the right hint came from the client. In Monitor’s API, a manufacturing operation has a field called BundleId, which the API only describes as “a generated id common to a collection of operations”. When a planner includes rows in a plan, they get a shared BundleId. On ordinary rows the field is empty.
That wasn’t clearly documented either, and a wrong filter would have quietly dropped parts that are needed. So before relying on it I compared the colour-marked and ordinary rows on Monitor’s screen with the database records across many work orders and operations. Every coloured row had a BundleId and no ordinary row did. Only then did I add the filter BundleId IS NULL. Now only parts nobody has included in a plan yet reach the list.
Material
The list also had to show whether a part's material has been issued: the same “R” or “C” mark Monitor shows on screen.
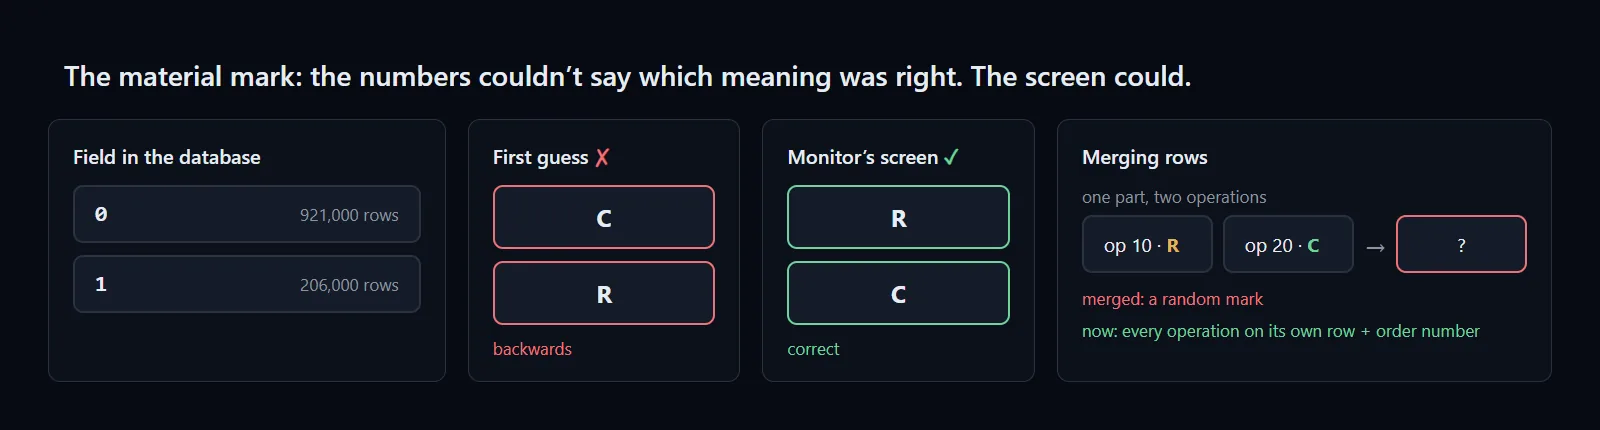
In Monitor, “R” means the operation needs material that hasn’t been issued yet, and “C” means it has. In the database I found a field on the operation with only two values, 0 and 1. The obvious guess was that 1 means “material missing”.
What didn’t work: the guess was exactly backwards. When I compared the result with Monitor’s screen, every “R” row was a “C” in the list. Across the whole database there were about 921,000 rows with 0 and about 206,000 with 1, but the numbers alone couldn’t tell which meaning was right. Only the screen could.
The second trap was merging rows. One part can sit on several operations, one with its material issued and another without. Merge those rows and the database picks one of them at random, so the mark is sometimes right and sometimes wrong. Now every operation has its own row with the order number, so the mark always belongs to the right row.
Data quality
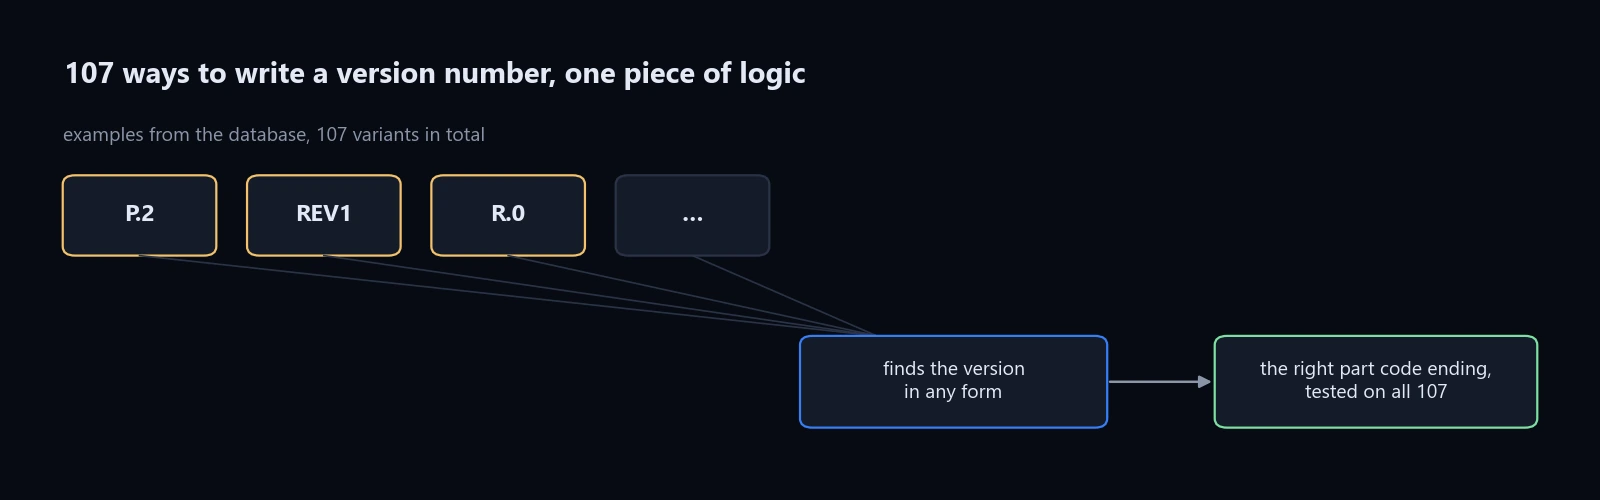
Part codes got the wrong ending, because the database wrote the revision number in 107 different ways (P.2, REV1, R.0 and plenty of typos).
In the list a part code has to look the same as in the drawing file names: part number, a dot and the revision, such as .r1 or .p0. The database keeps this in two places. Some parts have the revision inside the number already, others get it from a separate revision table through the order.
A simple find-and-replace was never going to work, because every new rule revealed the next special case. REV.1 has to become .r1, but PRE.0 has to become .p0, not .r0. If the revision is already in the number it mustn’t be added twice, or you get an ending like .r0.r0. Inside the number the revision can be upper case (.R3, .P1), and then it has to be lowered so the list doesn’t look messy. With no revision at all, the part gets .p0.
I wrote logic that finds the revision number in any of those forms and tested it against all 107 variants. Every part now gets the right ending.
Adding the revision brought one more error: the database connection (ODBC) stopped the query with “Invalid string or buffer length”. I narrowed it down step by step. The base query worked, joining the revision table worked, and the error only appeared once the revision text was joined onto the part code. The fix was to convert the text fields to a fixed length before joining them, which the connection can handle.
Logic
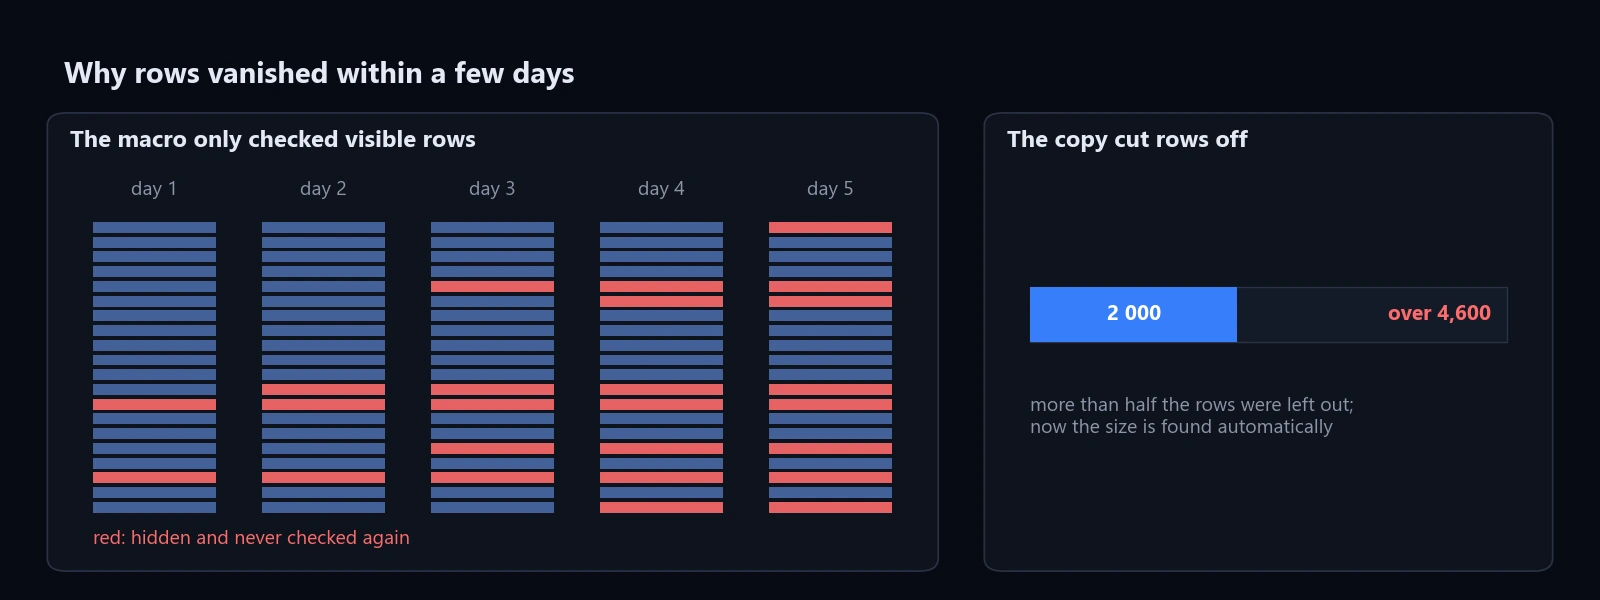
Rows disappeared from the list over a few days and never came back.
The macro only checked rows that were currently visible. Once a part was planned and hidden, it was never looked at again, even if it was later taken out of the plan. One test run couldn’t catch this, because hidden rows piled up slowly over days. Now every row is made visible and checked again before each filter pass.
The old copy step also stopped at 2,000 rows when there were over 4,600. It now works out the size of the data by itself.
Dates
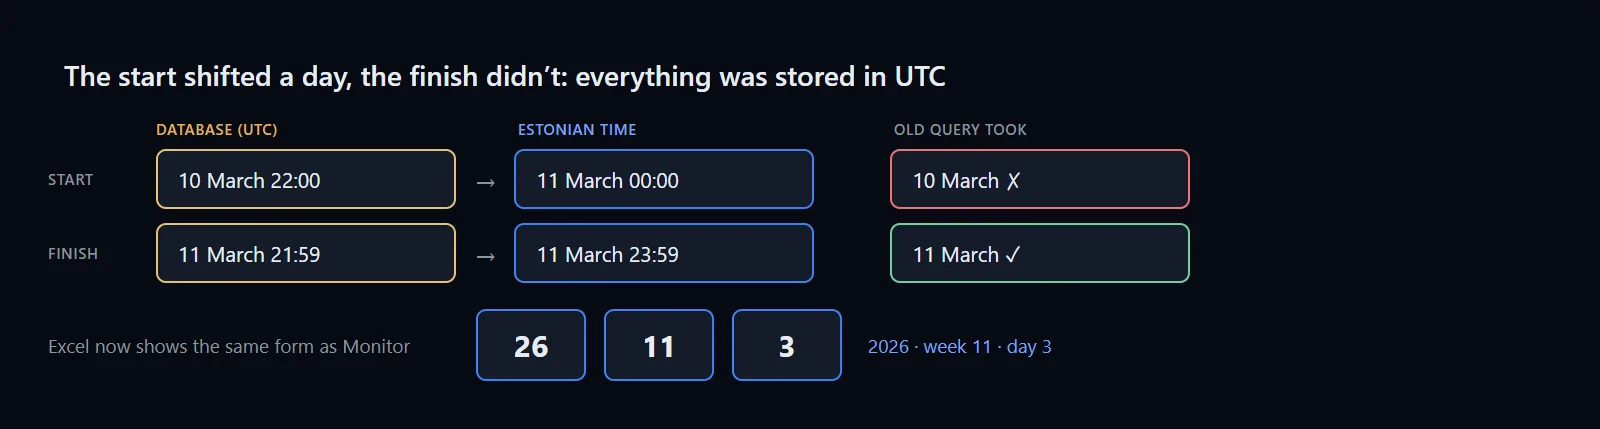
The planned start date was sometimes a day off, even though the finish date looked right.
Monitor stores times in UTC. An operation that starts on 11 March Estonian time is stored as 10 March at 22:00. The old query simply took the date part, so the part got a start one day early. The finish date looked right because it’s stored at 21:59 and stays on the same day in UTC. Now the time is converted to Estonian time before the date is taken.
Monitor shows dates as year, week and day: 26113 is day 3 of week 11 of 2026. The list now shows them the same way, so nobody has to convert in their head. I also put the columns in the same order as in the production software. I also added the order number column, so you can see when the same part sits on two work orders and only one of them is planned.
Reliability
Nobody could tell whether the numbers on screen were fresh or hours old.
The file refreshes when it opens and then every two minutes. The time of the last refresh is always visible and turns red if the connection drops.
Some bugs came from Excel itself. Refreshing a data connection can move columns around, and OneDrive’s autosave can kick in while a macro is running. I added error handling and a guard against autosave, so an interrupted run can’t leave Excel in manual calculation mode or save a half-finished result.
Speed
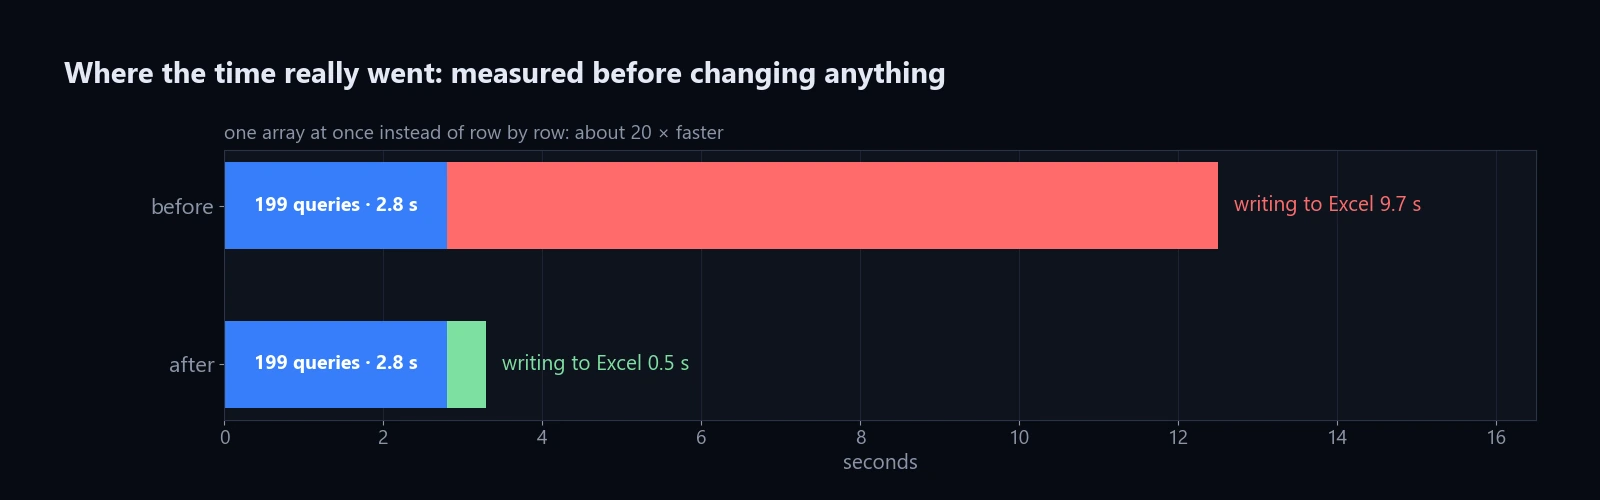
Refreshing was slow, and everyone blamed fetching data from the production software.
I measured before changing anything. All 199 requests together took only about 2.8 seconds. The real slowdown was Excel itself, where data was written one row at a time. Writing it all at once as one array made the Excel part about 20 times faster: from 9.7 seconds to 0.5.
Delay
The list was also meant to show the same delay in working days that the Monitor priority plan shows on screen.
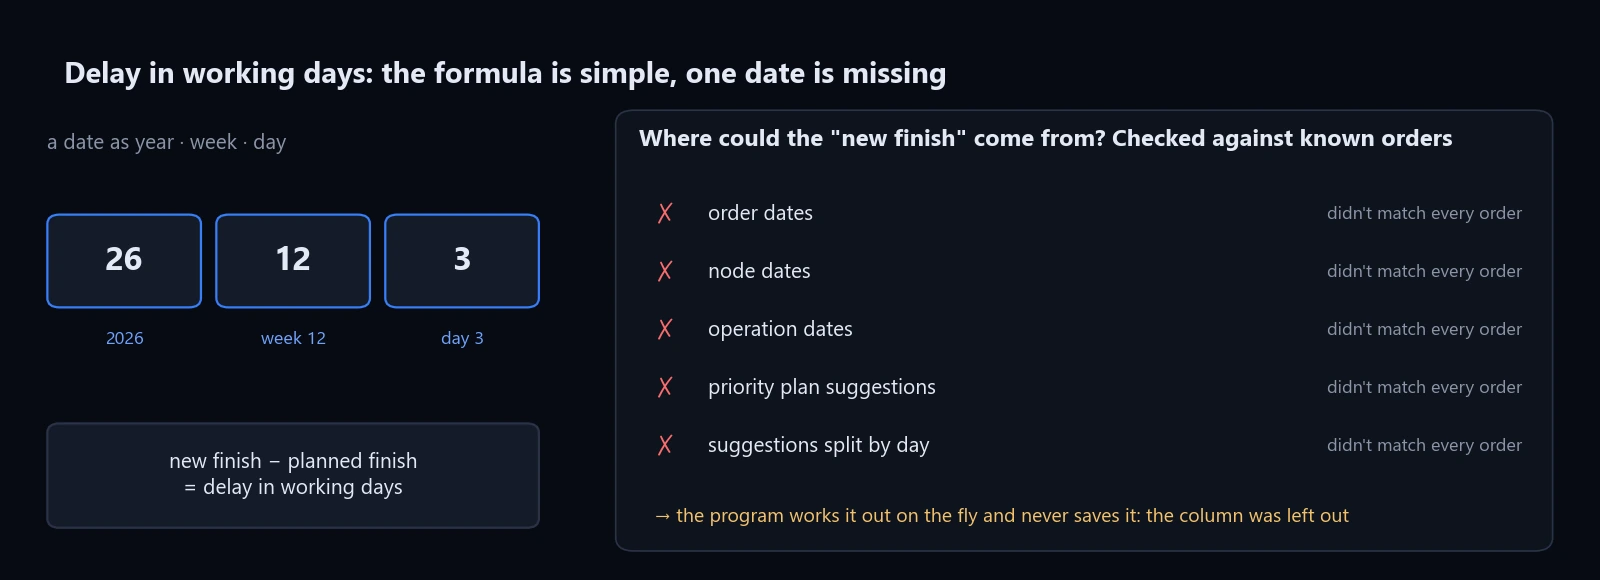
The formula itself is simple: the difference between the new finish date and the planned finish date in working days, in the same year-week-day form Monitor uses. The hard part was finding the new finish date itself.
What didn’t work: the first formula gave the right answer (−2) on exactly the order I tried it on. On the next order, where the screen showed 0, the same formula gave −9. From then on I checked every candidate against several orders at once: the order, node and operation dates, the operation’s planned-days table and the priority plan’s suggestion tables. Some candidates gave the right answer for some of the orders, but none gave it for all of them.
The clearest case was an order where the screen showed −8 working days. The new finish date was at the end of March, but every date that order had in the database was in April. The date I was looking for simply wasn’t there. I also tried to calculate it myself with the remaining-time formula from Monitor’s manual, but the operation had about three minutes of work left. That can’t explain a shift of almost two weeks.
In the end the manual gave the answer: the new finish date is recalculated every time from the current time, the remaining time of every operation ahead of it on the priority plan, and the capacity of the work centres. It’s a small planning engine inside the Monitor program. The result is never saved to the database, and the API doesn’t return it either. The database does have a NewFinishDate field, but it was empty on all of roughly 1.16 million rows.
A simplified stand-in, days from today to the planned finish, gave −30 on the same order instead of −8. Rather than put a number into the list that is sometimes right and sometimes wrong, I left the column out and wrote down why. A wrong delay number is worse than no number.
Result
Laser cutting now gets a list from Monitor that refreshes itself, contains only unplanned parts and warns when the data is old. Planning itself stays in Monitor. The list only gathers what the laser needs from it, in exactly the form it needs.
I was also honest about what couldn’t be done. Two values are worked out by Monitor only for a moment and never saved: the matching field was empty on all ~1.16 million rows. Instead of making numbers up, I wrote down why and suggested realistic next steps.
Nobody has to write data out of Monitor by hand, reformat it or check whether a part has already been planned any more.
What is it worth? In metal fabrication, one missed or double-planned part means an idle machine, a rush order or a late delivery, often costing hundreds to thousands of euros each time. A list that always takes fresh data from Monitor and leaves out parts already planned cuts exactly those mistakes. (Estimate based on a typical subcontract manufacturer, not the client’s books.)
What's next
The logical next step is automatic alerts for late orders and missing materials, straight from Monitor data.